How to run a measurable B2B AI employee pilot
A simple scorecard: choose one job, check the answers and measure business results before you give an AI employee more work.
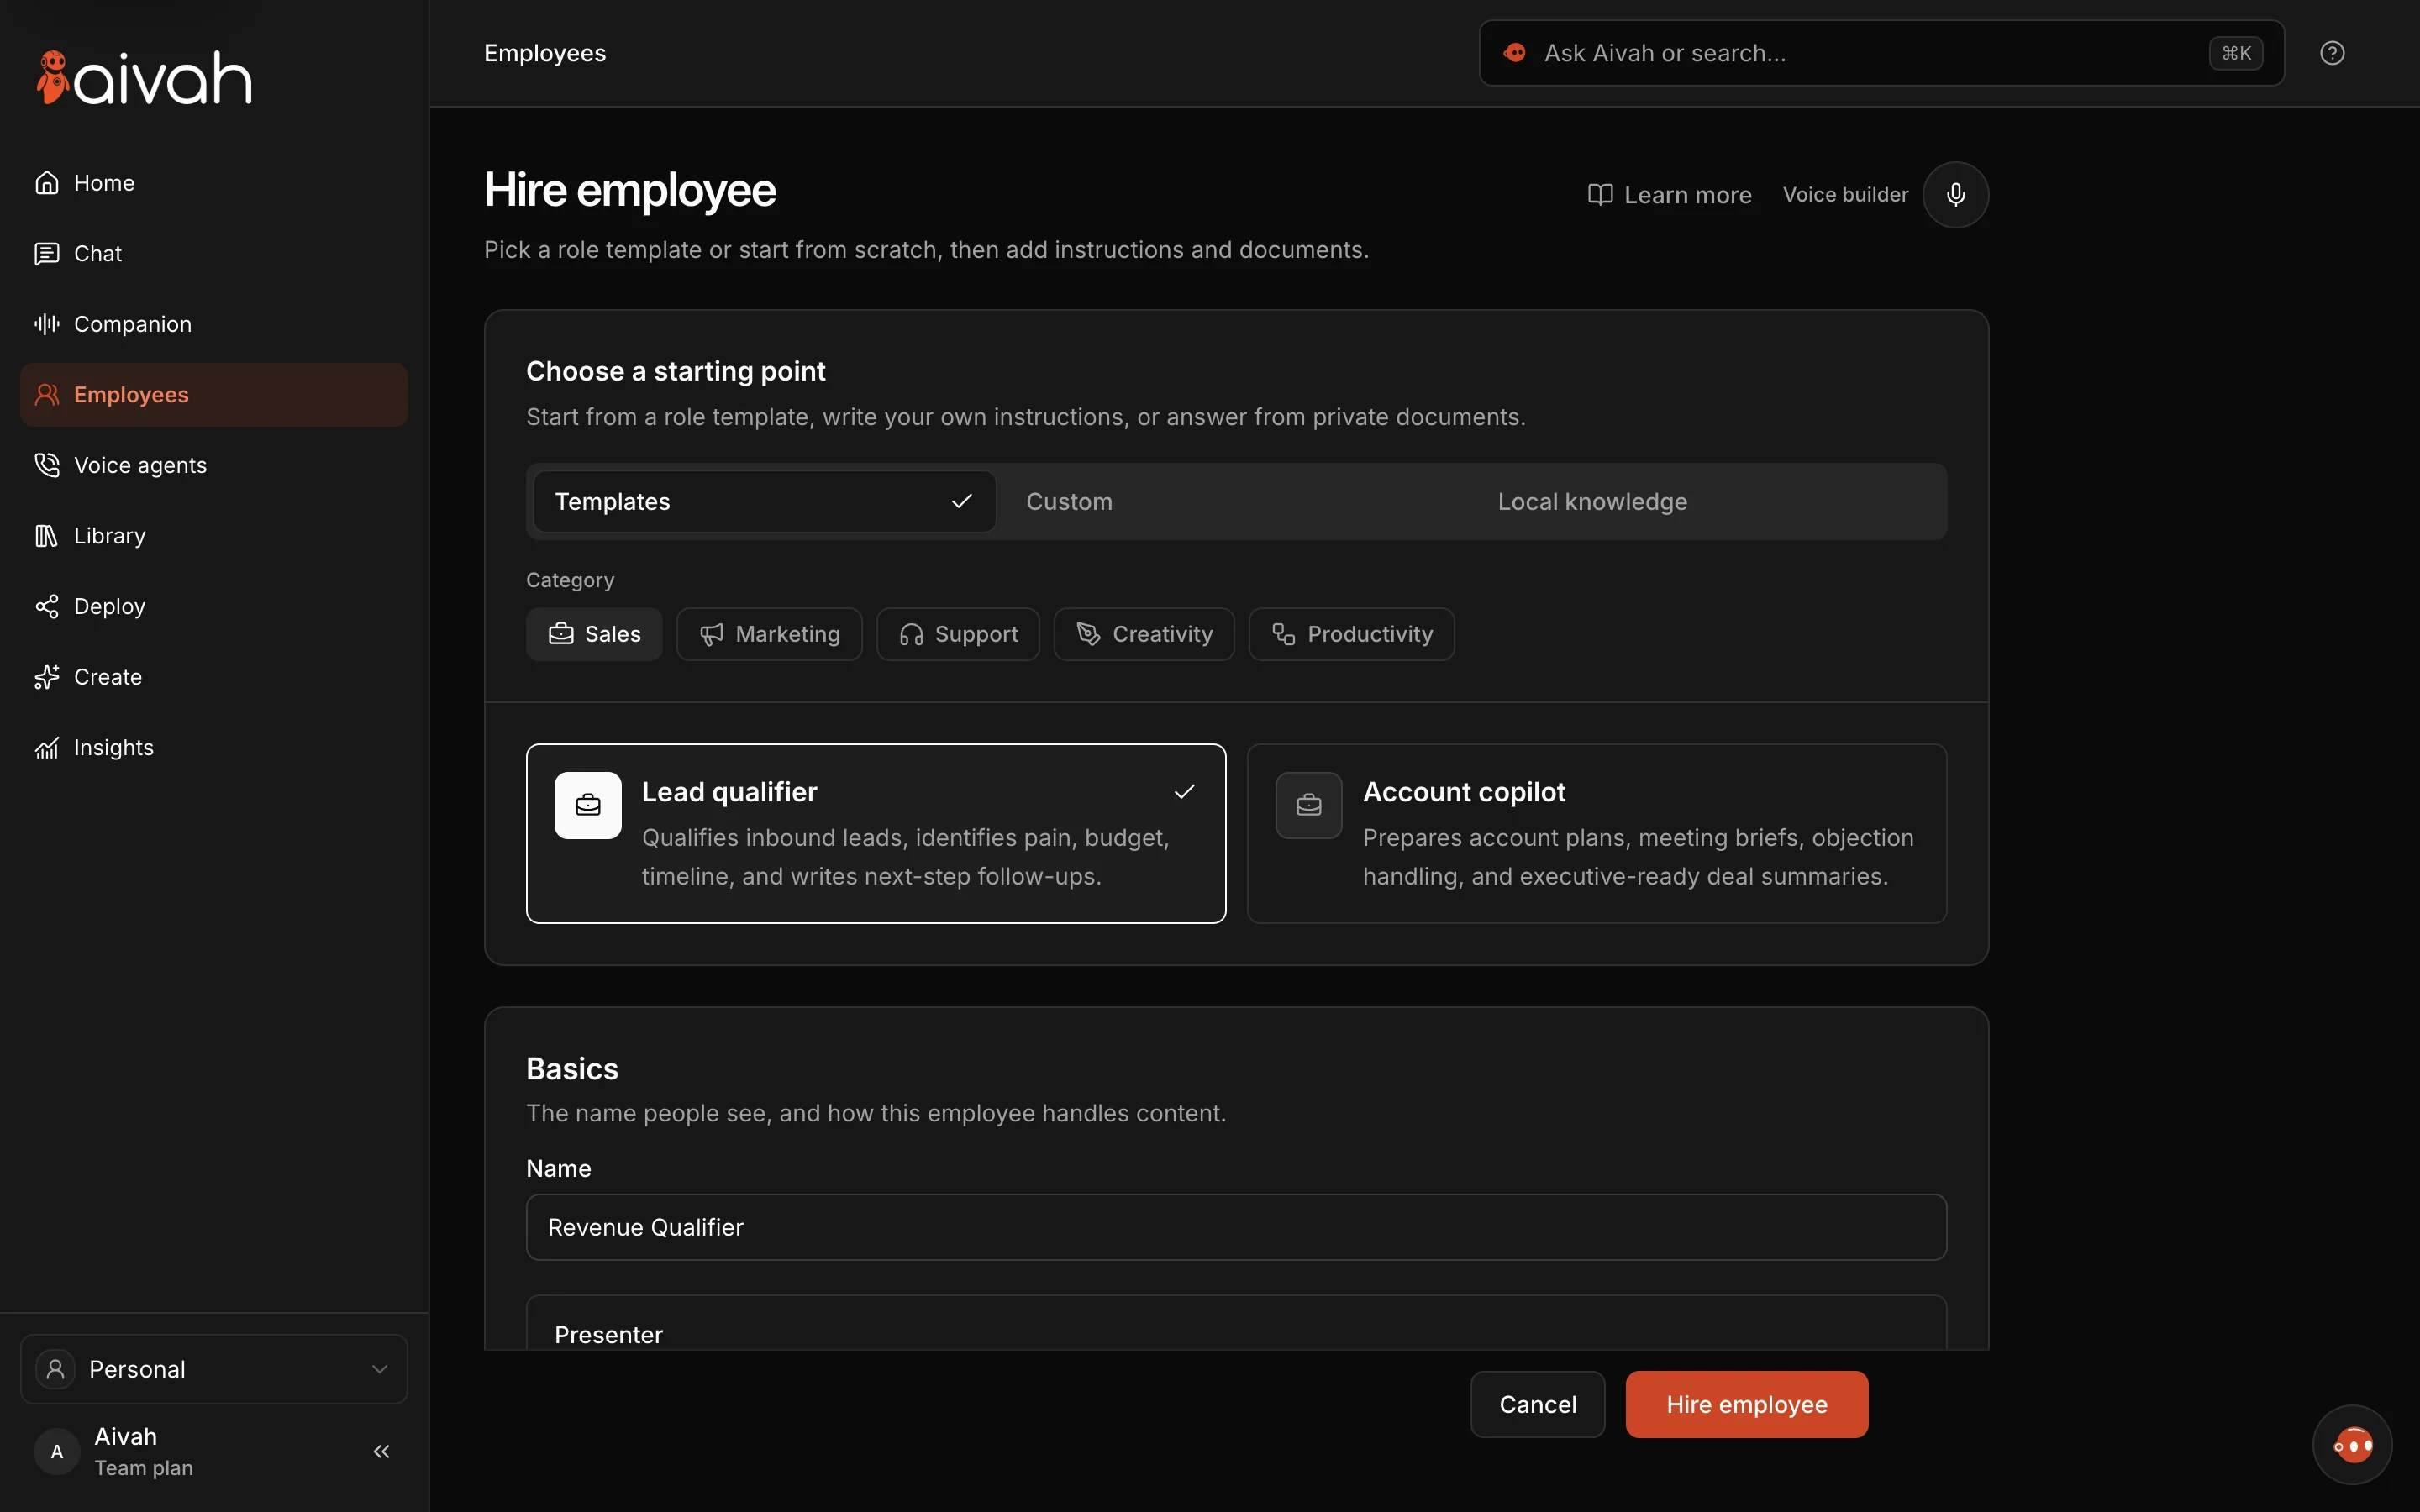
The Aivah app today.
Choose one job and one owner
Pick one audience, one business problem and one person in charge of the pilot. “Improve customer experience” is too broad to test. “Help new customers finish setup and send open issues to support” gives your team something it can watch.
Set the scope before you choose how it looks. Decide what the employee may answer, which actions it may take and which decisions belong to people.
Record a starting point you can compare
Measure how things work today over a typical period. Count eligible customers, finished outcomes and open cases. Write down who is included, so you compare the same group after launch.
For sales, keep visitors, enquiries and accepted leads apart. For support, keep chats, solved problems and reopened issues apart. For onboarding, keep new accounts apart from the first useful result. Don’t merge them into one success number.
Build a test set before rollout
Prepare typical questions, each with an expected answer and its source. Include unclear requests, missing facts and requests outside the employee’s job. Use the words customers really use, not only the wording in your documents.
Check real answers against the source. Record the date, source version, question, answer and the reviewer’s verdict. Test connected actions separately by looking at the system they reach.
Use a balanced scorecard
Choose one main business result and a few quality checks. Set your own pass marks based on the risk and how things work today. These are things to measure, not Aivah results.
- Result: an accepted lead, a solved issue or an activation milestone.
- Quality: the share of correct answers in a reviewed sample.
- Customer effort: repeated questions and the time to a useful answer.
- Handover: whether the right person gets enough detail.
- Reliability: failed actions, duplicate records and connection errors.
- Running cost: real usage, plus the time spent reviewing and keeping it current.
Expand once the evidence is clear
Compare like-for-like traffic, and wait for enough finished journeys to mean something. Small samples, campaign changes and internal tests can make a gain look bigger than it is. A before-and-after comparison alone doesn’t prove AI caused the change.
Keep a log of fixes and of failures you haven’t solved. Move to another page or job once the first one works and someone looks after it. Don’t add more work to a pilot that isn’t reliable yet.